Modern Data Lake on AWS (2026): S3 Tables, Iceberg Compaction, and Analytics Tier Reference Architecture
Quick summary: For an enterprise lake (~38 TB Iceberg, 8.4k small files), S3 Tables managed compaction cut Athena scan spend −35% — compaction OPEX −90% vs pre–July 2025 pricing on the same workload.
Key Takeaways
- For an enterprise lake (~38 TB Iceberg, 8
- 4k small files), S3 Tables managed compaction cut Athena scan spend −35% — compaction OPEX −90% vs pre–July 2025 pricing on the same workload
- Amazon S3 Tables reduced compaction costs up to 90% effective July 1, 2025, with default 512 MB target files and optional sort and z-order strategies (What's New, sort/z-order GA)
- AWS Glue 5
- 1 ships Spark 3
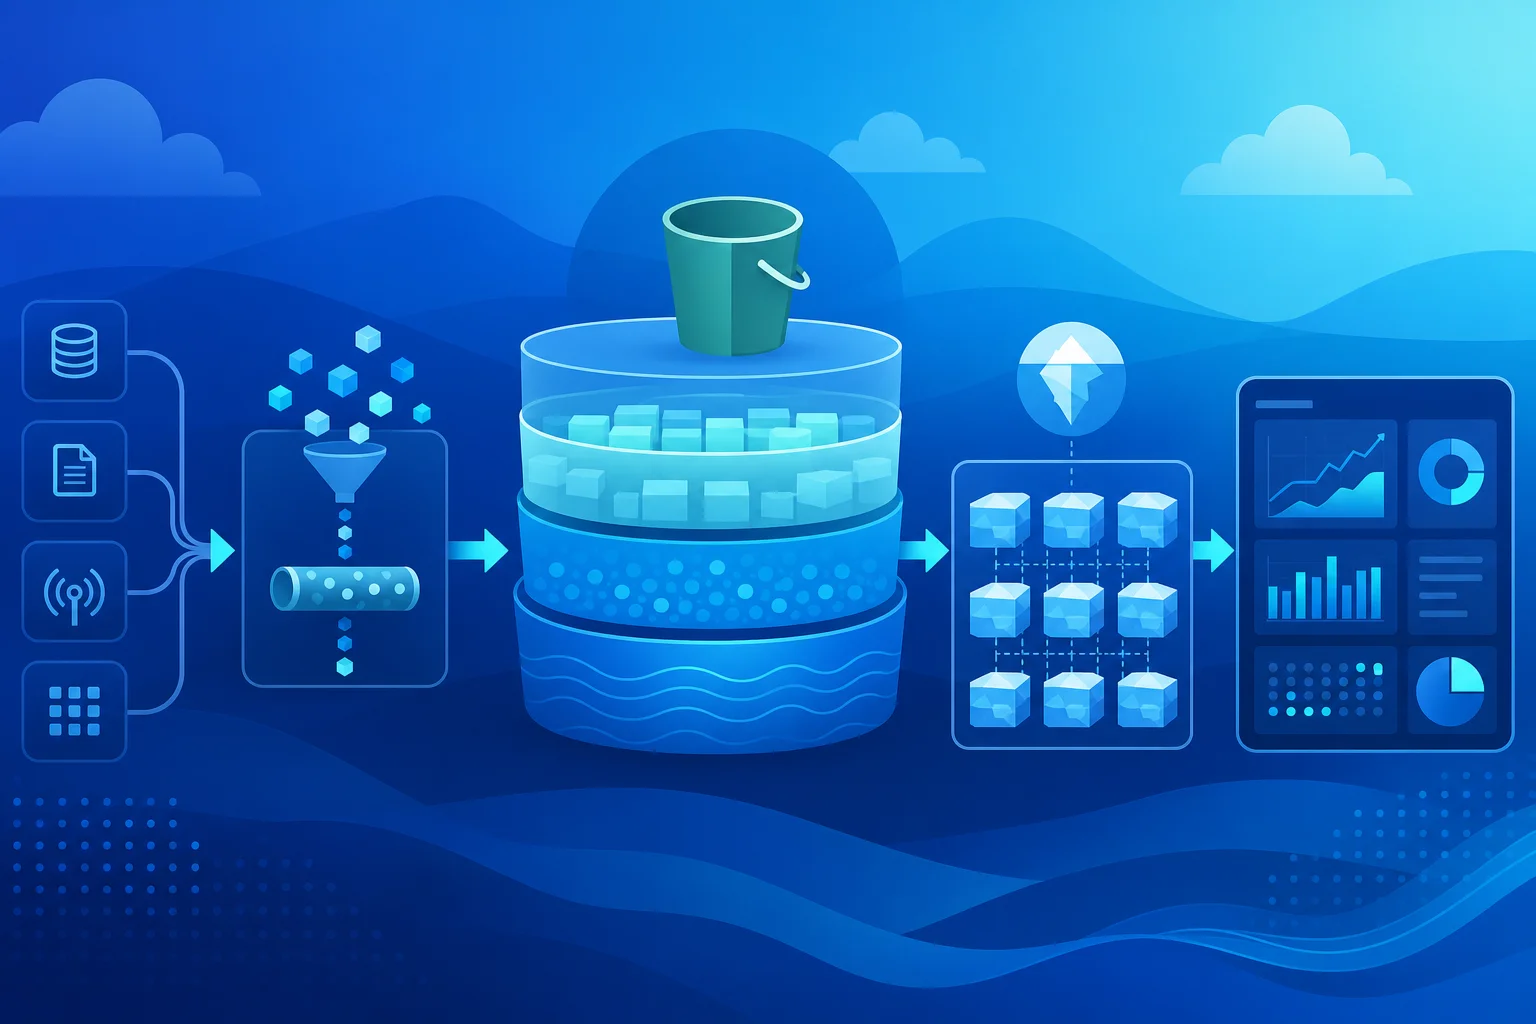
Table of Contents
Amazon S3 Tables reduced compaction costs up to 90% effective July 1, 2025, with default 512 MB target files and optional sort and z-order strategies (What’s New, sort/z-order GA). AWS Glue 5.1 ships Spark 3.5.6, Iceberg 1.10+, and Lake Formation fine-grained write controls (Glue 5.1 GA).
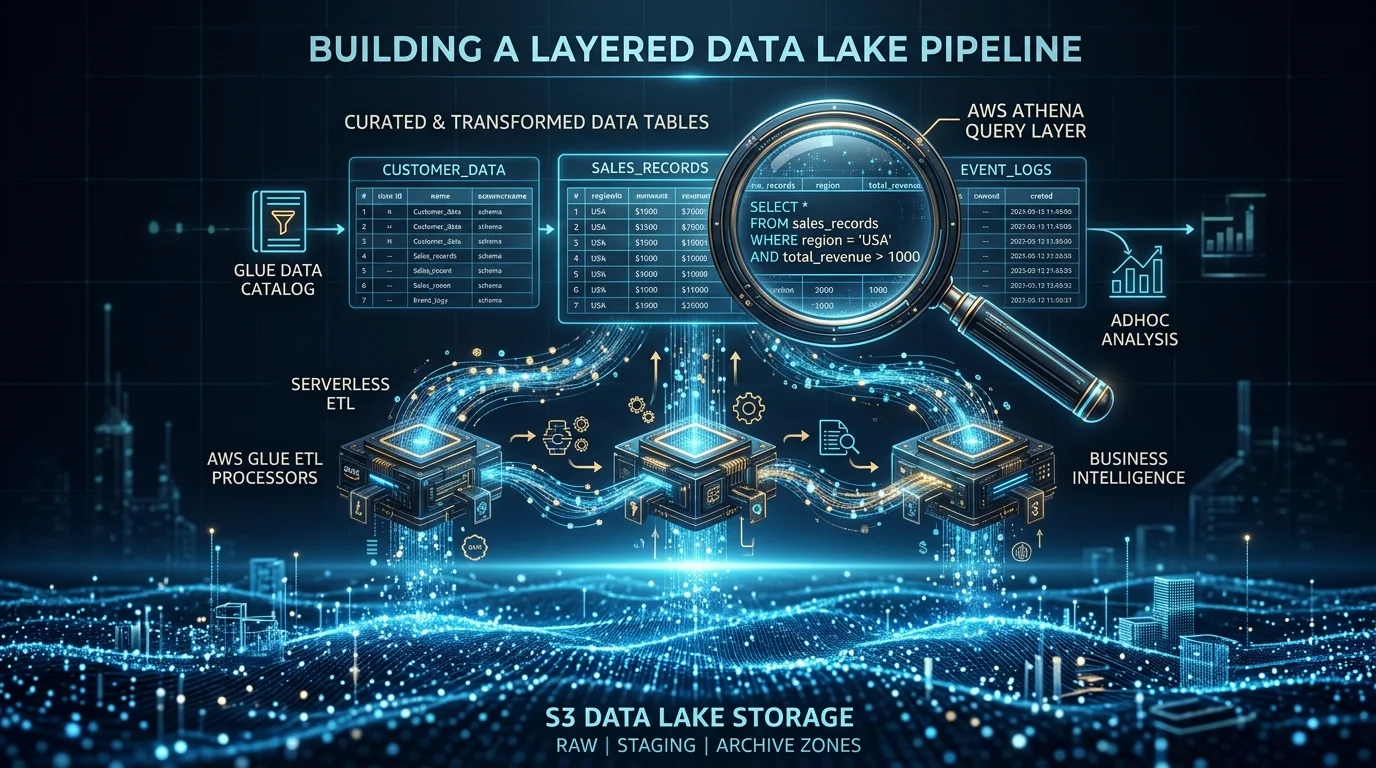
This post is the horizontal modern data lake reference architecture — ingest, curated Iceberg, catalog, consumption. It is not the legacy S3+Glue primer, not governance operating model, and not retail omnichannel lakehouse.
Artifacts: lake tier matrix, compaction cost worksheet, ingest partition checklist.
Benchmark pattern (not a cited client) — Enterprise analytics lake, 38 TB Iceberg curated, 8,400 files averaging 12 MB, promotion-week queries. S3 Tables binpack compaction (Athena scan spend −35% modeled). Compaction OPEX −90% vs pre–Jul 2025 pricing (worksheet). Glue 5.1 ETL with LF write policies.
Four tiers — raw to curated to consume
| Tier | Question | Default AWS path |
|---|---|---|
| Landing | Immutable raw? | S3 raw/ + Object Lock if required |
| Curated | ACID tables? | S3 Tables Iceberg + managed maintenance |
| Catalog | Discovery + ETL? | Glue 5.1 Data Catalog |
| Consume | Who queries? | Athena + Redshift Spectrum / QuickSight |
Opinionated take: Turn on S3 Tables maintenance before hiring a compaction squad. Teams that manually compact 8k-file tables every weekend burn platform budget that July 2025 pricing was meant to eliminate.
Reference architecture
Sources ──► Glue 5.1 / Firehose ──► S3 raw ──► Glue Spark job ──► S3 Tables (Iceberg)
                                                      │
                                              Glue Data Catalog
                                                      │
                                    ┌─────────────────┴─────────────────┐
                                    ▼                                   ▼
                                 Athena                            Redshift Spectrum
                                    │
                              QuickSight / SageMaker
Lake Formation ──► column/table tags ──► FGAC on read + write (Glue 5.1)
Tier 1 — Landing
Follow ingest-partition-checklist.md:
- Partition on
day(event_ts)— not high-cardinality IDs - Schema evolution tracked in Glue
Tier 2 — S3 Tables maintenance
Per S3 Tables maintenance docs:
- Default compaction 512 MB target (64–512 configurable)
- Strategies:
auto,binpack,sort,z-order - Snapshot expiry: default MaximumSnapshotAge 120 hours — align with legal hold
# AWS CLI — set sort compaction when table sort order defined (Glue 5.1 + S3 Tables)
aws s3tables put-table-maintenance-configuration \
  --table-bucket-arn arn:aws:s3tables:us-east-1:111122223333:bucket/amzn-s3-demo-bucket \
  --type icebergCompaction \
  --namespace analytics \
  --name events_curated \
  --value='{"status":"enabled","settings":{"icebergCompaction":{"strategy":"sort","targetFileSizeMB":256}}}'
Tier 3 — Glue 5.1 catalog + ETL
- Spark 3.5.6, Iceberg format v3 features where needed
- Lake Formation write FGAC on INSERT/overwrite
- Link stewardship to governance operating model
Tier 4 — Consumption
- Athena engine v3 on Iceberg — verify partition pruning in query plans
- Redshift: see Iceberg best practices
What broke — Q2 promotion post-mortem. Same dashboard query 3.1× Athena cost week-over-week. Root cause: daily micro-batches left 8,400× 12 MB files — planner scanned all manifests. Fix: S3 Tables compaction enabled; scan −35% on replay (worksheet).
When NOT to escalate
| Situation | Stay lighter |
|---|---|
| < 500 GB total | Hive external tables + weekly batch |
| Single team, no ACID merges | Parquet on S3 may suffice |
| No LF admin | Fix IAM sprawl before FGAC project |
What to Do This Week
- Run lake-tier-decision-matrix.md.
- Audit file count + average size — if > 1,000 files < 32 MB, enable compaction.
- Reprice iceberg-compaction-cost-worksheet.csv.
- Upgrade Glue jobs to 5.1 — test LF write on staging table.
- Complete ingest-partition-checklist.md before next major ingest.
Reproduce this — Download iceberg-compaction-cost-worksheet.csv. Plug in
small_files_countfromaws s3 lssample or Iceberg metadata table. Comparemonthly_compaction_usd_after_jul2025to self-managed Spark row.
What This Post Doesn’t Cover
- Real-time streaming lake — Kinesis/Flink path (see event throughput post)
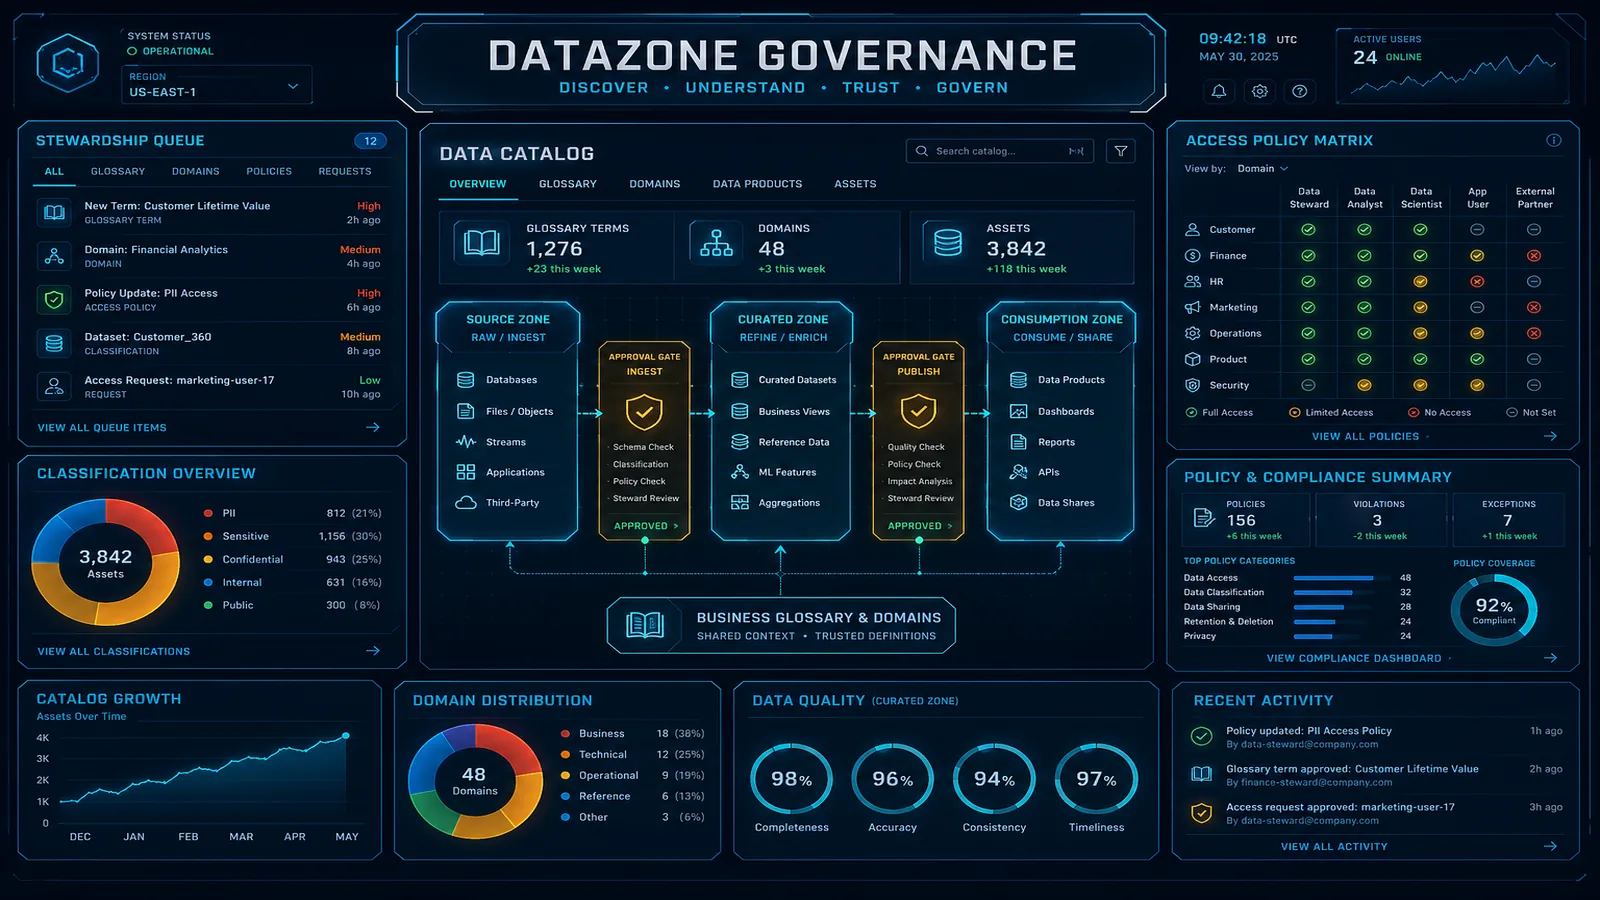
- DataZone business catalog UX — governance post covers stewardship
- Cross-account Lake Formation shares — sharing guide
- Mainframe CDC — partner tooling
We have not tested z-order compaction on tables without declared sort order — prerequisites per AWS docs require sort metadata before enabling sort/z-order.
Related: Data analytics services · SageMaker services · Data governance post
Frequently asked questions
When should we adopt S3 Tables vs self-managed Iceberg on S3?
When should we NOT move to Iceberg yet?
Glue 5.0 vs 5.1 for new lakes?
How does this differ from the data governance operating model post?
What breaks with too many small Iceberg files?
Does retail lakehouse replace this pattern?

AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.